VAnnotatoR
- Last Updated: 1/21/2021 12:00:00 AM
- Site: https://www.texttechnologylab.org/applications/vannotator/
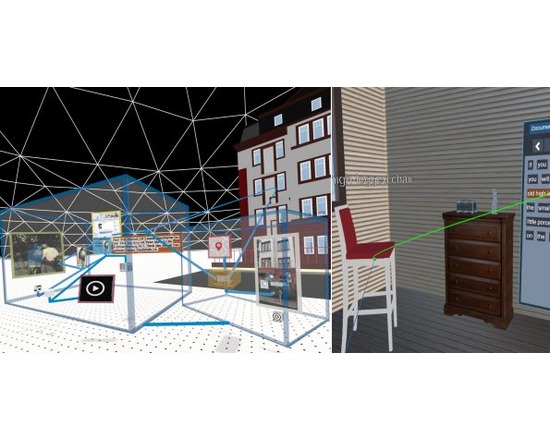
VAnnotatoR is a system that massively supports the annotation of multimedia, multimodal networks of linguistic and object-related data in virtual 3D environments.
VAnnotatoR allows for segmenting and linking texts and images with other multimedia, multimodal data to ultimately create spatial hypertexts. It can be used to support concrete technical applications, e.g. the reconstruction of 3D scenes from texts as a preparatory step for the training of Text2Scene systems, or for applications in the digital humanities, such as the spatial reconstruction and linking of historical scenes or biographies with corresponding media content, such as images or 3D reconstructions of historical buildings. The entire system is interactively accessible with VR glasses in Virtual Reality (VR) and can be controlled and experienced accordingly. VAnnotatoR uses TextAnnotator as technological backbone and thus all its functions for annotation, task management, annotation evaluation as well as for collaborative and simultaneous processing of resources. Furthermore, VAnnotatoR uses TextImager to benefit from its NLP routines for automatic text analysis. VAnnotatoR is implemented on the basis of Unity3D and OpenVR and therefore runs with both systems and several VR glasses – it was tested on Oculus Rift, Oculus Rift S, Oculus Quest, HTC Vive and HTC Vive Cosmos under Windows 10.
A demonstration of its usage can be found here https://www.youtube.com/watch?v=BBUg8mHT0iI
Documentation
Creator(s): Text Technology Lab
Creator's Site: https://www.texttechnologylab.org/
Creator's Email:
Repository:
Attributes
- Type of analysis: Visualization Natural Language Processing Analysis Annotating
- Type of license: Free
- Ease of Use: Easy
- Warning: Beta
- TaDiRAH Goals: Analysis
- TaDiRAH Methods: Annotating Content Analysis Network Analysis Spatial Analysis Visualization
List this tool appear on
Rating
Suggested Tools
Comments