Site is under maintenance. Please login, thank you.
CMU-Cambridge Statistical Language Modelling Toolkit
- Last Updated: 12/5/2013 12:00:00 AM
- Site: http://svr-www.eng.cam.ac.uk/~prc14/toolkit.html
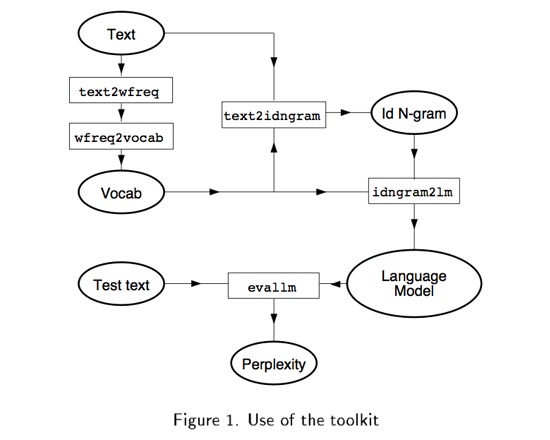
The CMU-Cambridge Statistical Language Modelling Toolkit is a longstanding set of Unix tools offered by Carnegie Mellon University and Cambridge University. It includes functions for word frequency, n-grams, vocabulary and words marked as 'context cues'. Version 1 was written by Roni Rosenfel and released in 1994.
Documentation
Attributes
- Type of analysis: Analysis
- Type of license: Free
- Background Processing: Not Applicable
- Web Usable: Software you Download and Install
- Ease of Use: Moderate
- Historic Tool (developed before 2005): Influential
- TaDiRAH Methods: Other (analysis) Statistical Analysis
List this tool appear on
Rating
Suggested Tools
Comments
For more information about the CMU-Cambridge Statistical Language Modelling Toolkit, please see the following paper by its creators:
Clarkson, P. R. and R. Rosenfeld. \"Statistical Language Modeling Using the CMU-Cambridge Toolkit.\" Proceedings of the ESCA Eurospeech, 1997. Web.
The website is down. An archived version:
https://web.archive.org/web/20150307070601/http://svr-www.eng.cam.ac.uk/~prc14/toolkit.html